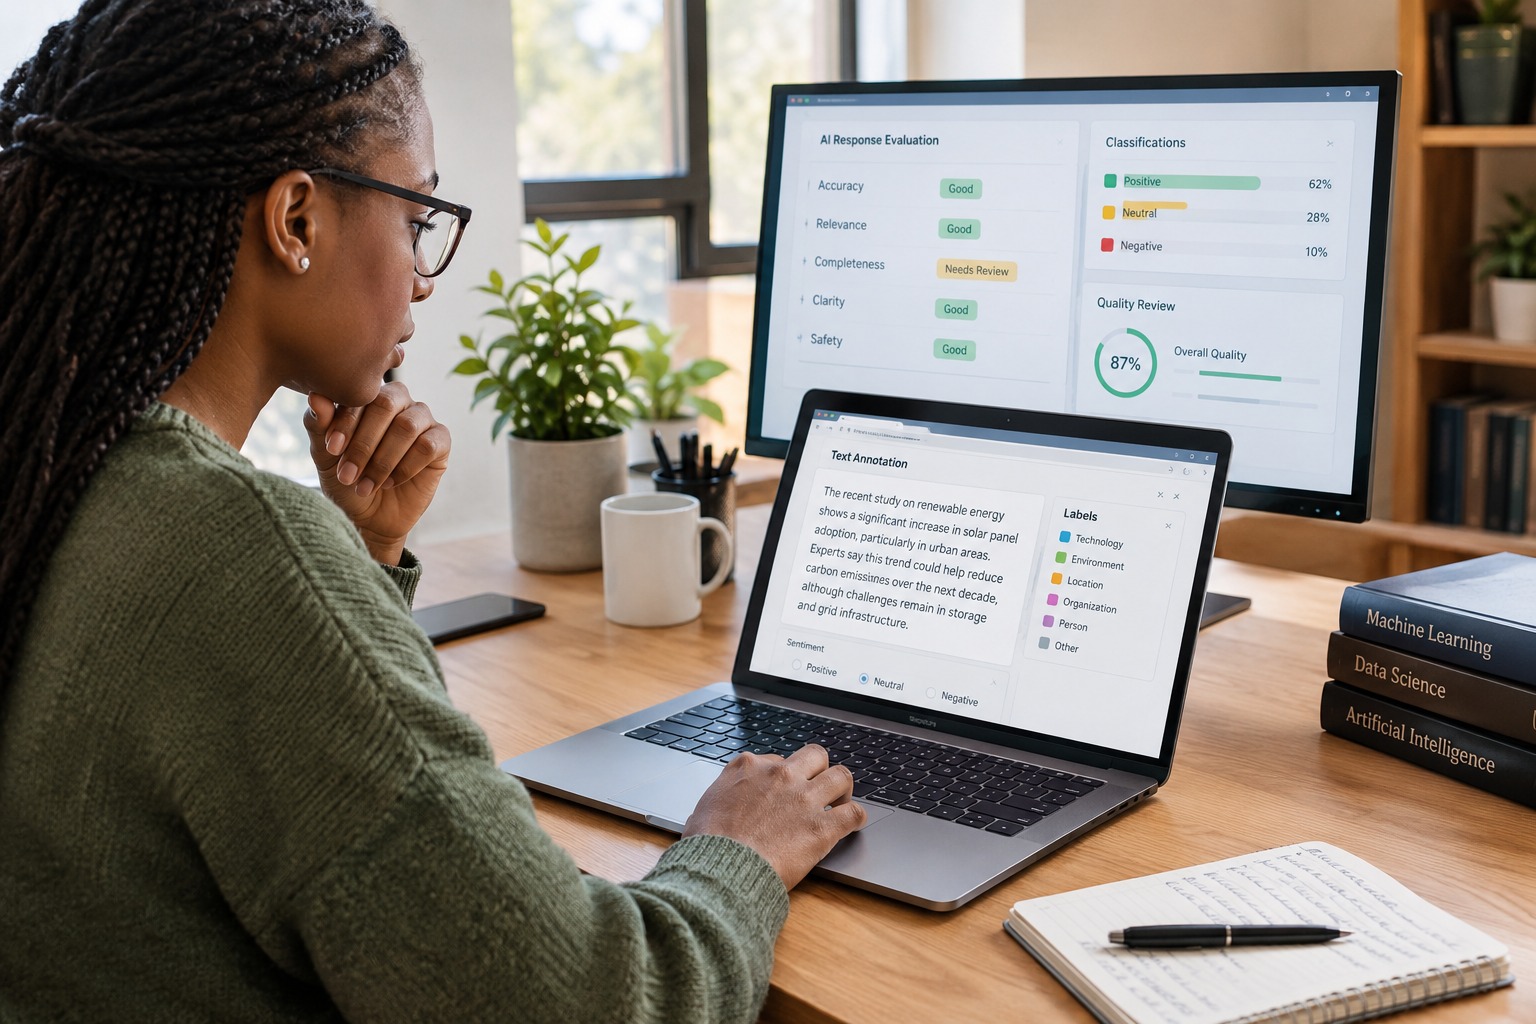
An AI system can process thousands of examples in seconds, but that does not automatically mean it understands what those examples mean. Someone still has to identify the correct answer, spot misleading information, explain why a response is wrong, or decide which of two answers is more useful.
That work often happens far from public view. While people interact with AI assistants, image generators, translation tools, and automated services, human data annotators help prepare the information these systems learn from and evaluate how well they perform.
Their work can involve reviewing text, labeling images, checking AI-generated answers, transcribing speech, or assessing whether a model follows instructions. Some tasks require little specialist knowledge, while others demand expertise in fields such as law, medicine, finance, languages, or software development.
The importance of this workforce is easy to overlook because the finished product gets the attention. Yet an AI model's performance depends partly on the quality of the data used to train and evaluate it.
For people seeking remote work, this also creates an opportunity to use existing skills in a different way. Understanding what data annotators actually do, and where their judgment makes a difference, is a useful starting point for anyone considering AI training work.
What Is AI Data Annotation?
AI data annotation is the process of adding labels, classifications, explanations, or other useful information to data so that machine learning systems can learn from it or be evaluated against it.
The type of annotation depends on what the AI system needs to do.
For example, an image-recognition model may need labeled pictures to learn to identify road signs. A speech-recognition system may need audio recordings paired with accurate transcripts. A language model may be evaluated using human judgments about whether its answers are correct, relevant, clear, and safe.
Google's People + AI Guidebook explains important considerations in collecting and evaluating training data, including data quality, labeling errors, bias, and the treatment of data workers.
The central point is simple: data does not become useful for every AI task merely because it exists. It often needs to be selected, organized, checked, or evaluated for a specific purpose.
What does a data annotator actually do?
Depending on the project, an AI data annotator may:
Label objects in photographs or videos.
Transcribe recorded conversations and identify individual speakers.
Categorize text according to its subject, meaning, or purpose.
Review AI-generated answers for factual accuracy.
Compare two model responses and identify the stronger one.
Check whether an answer follows the instructions in a prompt.
Identify harmful, misleading, irrelevant, or biased content.
Write examples that help a model handle particular questions or situations.
Flag unclear cases that require further review.
These responsibilities are not identical across companies. A basic image-labeling project may involve applying predefined categories, while a specialist language-model evaluation project may require detailed written reasoning.
That distinction matters when looking for work. A job advertised as data annotation may involve repetitive labeling, complex evaluation, or a combination of both. The title alone does not tell you how demanding the work will be.
Why Human Data Annotators Still Matter When AI Can Generate Its Own Content
AI systems can produce large amounts of text, images, audio, and code. It is tempting to assume that they can also generate everything they need to improve themselves without much human involvement.
That assumption overlooks a crucial problem: generating an answer is not the same as knowing whether the answer is good.
A model can produce a confident explanation that contains a factual error. It can follow the wording of a request while missing the person's actual intention. It can generate a grammatically correct sentence that sounds unnatural to a native speaker, or write code that appears convincing but fails when executed.
Someone must establish what counts as a good answer for the task at hand.
- Human judgment helps distinguish plausible answers from correct ones
Consider an AI assistant asked to explain a legal concept to a beginner. Its response may sound professional and contain familiar legal terminology. However, it might confuse two related doctrines or describe a rule without mentioning an important limitation.
A reader without legal training might accept the explanation because it sounds authoritative. A qualified legal reviewer could identify the problem, explain why it matters, and assess whether the response accurately answers the question.
The same principle applies in other fields. An accountant can identify an incorrect financial calculation. A software developer can test whether a proposed solution works. A language specialist can assess meaning and natural expression.
Human reviewers contribute the knowledge needed to assess an answer against standards that matter in the real world.
- Human feedback can shape model behaviour
Annotation is not limited to preparing examples before a model is trained. Human feedback can also help developers refine how models respond.
Google DeepMind's research on learning through human feedback describes an approach in which people compare a system's behaviour and provide preferences that help guide learning. Its work on building safer dialogue agents also explores how human feedback can help improve the usefulness and safety of conversational systems.
In practical terms, people may be asked to compare responses to the same question and identify which one better meets the requirements.
One answer might be more accurate but unnecessarily complicated. Another might be clear but omit a critical detail. A good evaluation process gives reviewers criteria for deciding which response performs better and why. The feedback can then support the development and evaluation of systems that are more useful for their intended purposes.
Human feedback is not a guarantee that a model will always behave correctly. Its value depends on the quality of the judgments, the way developers use them, and how the system is tested afterward.
The Different Types of Work Human Data Annotators Perform
The term data annotation covers several types of work. Understanding the differences can help job seekers identify roles that match their experience and expectations.
1. Text annotation and language evaluation
Text annotators work with written material. They may classify customer messages, identify topics, assess sentiment, label entities such as names and locations, or check whether text meets specific guidelines.
In AI training projects, the work can extend to reviewing model-generated responses. A reviewer might assess whether an answer follows instructions, contains unsupported claims, or responds appropriately to the question.
Language-focused tasks can suit people with strong reading comprehension, editing, research, writing, or linguistic skills. More advanced assignments may require specialist knowledge or the ability to explain complex judgments clearly.
2. Image and video annotation
Computer vision systems rely on visual data to identify objects, recognize patterns, or interpret scenes.
Annotators may draw boxes around vehicles, identify pedestrians, classify objects, or mark important details in video footage. Some projects require more detailed labeling, such as identifying actions or tracking an object across several frames.
Accuracy matters. If an annotator consistently labels an object incorrectly, those errors can affect the usefulness of the resulting dataset.
The exact requirements depend on the project. Some tasks are straightforward, while others require familiarity with specialized imagery or strict annotation tools.
3. Audio annotation and transcription
Audio annotation can involve transcribing speech, identifying speakers, adding timestamps, labeling background sounds, or marking unclear sections of a recording.
A transcription task may appear simple until the recording contains overlapping speakers, regional accents, technical terms, or background noise. In those cases, careful listening and consistent application of the project's rules become essential.
People with strong listening skills and proficiency in particular languages may find audio-related projects worth exploring. However, language requirements, equipment expectations, and accepted locations vary by project.
4. AI response evaluation
AI response evaluation focuses on judging the output of a model rather than simply labeling an existing piece of data.
A task might ask a reviewer to assess an answer for accuracy, relevance, completeness, clarity, or compliance with instructions. Some projects also require reviewers to identify harmful content or explain why a response fails a specified standard.
For example, a reviewer might receive two answers to a question about personal finance. One gives a clear explanation but invents a tax rule. The other is less polished but correctly identifies the relevant limitation. If factual accuracy is the main criterion, the second response may be preferable.
These projects reward careful reasoning. Reviewers need to follow the rubric, distinguish personal preference from objective quality, and support their decisions with evidence where required.
5. Specialist and domain-specific annotation
Some AI projects need more than general reading or labeling skills. They require people who understand a particular subject well enough to identify subtle errors.
Examples include:
Law: Reviewing legal explanations, identifying unsupported interpretations, or assessing whether an answer addresses the question.
Finance and accounting: Checking calculations, evaluating financial reasoning, and identifying incorrect assumptions.
Healthcare: Reviewing medical terminology or evaluating domain-specific material within the qualifications and boundaries required by the project.
Software development: Assessing code, debugging explanations, and checking whether proposed solutions meet technical requirements.
Education: Evaluating explanations, solving subject-specific questions, and identifying mistakes in learning materials.
Languages: Assessing translation quality, grammar, meaning, and culturally appropriate usage.
Not every project in these fields requires a licensed professional or advanced qualification. However, specialist assignments may have strict eligibility criteria, and applicants should never assume that general annotation experience automatically qualifies them.
What Makes a Good Human Data Annotator?
Speed can help someone complete more tasks, but speed alone does not make an annotator reliable. The quality of the work depends on how carefully the person interprets instructions, applies standards, and handles uncertainty.
Several skills are especially useful.
- Attention to detail
Small errors can matter. An annotator might overlook a negation, confuse two similar categories, or mark an answer as correct without checking a key claim.
Careful reviewers read instructions before beginning, check ambiguous cases, and avoid rushing through tasks simply to increase their completion rate.
- Research and fact-checking
Some evaluation tasks require reviewers to verify claims rather than rely on how convincing an answer sounds.
Useful habits include checking primary sources, distinguishing evidence from speculation, and recognizing when the available information is insufficient to support a conclusion.
The level of research required varies. Some projects prohibit external assistance, while others provide approved reference materials. Annotators should always follow the project's rules about research and tool use.
- Consistency
A reviewer should apply the same criteria to similar cases. If one response is marked incorrect for a particular mistake, another response containing the same mistake should receive comparable treatment unless the task instructions explain a relevant difference.
Consistency helps teams identify reliable patterns in the data and makes disagreements easier to investigate.
- Clear written explanations
Many evaluation tasks ask reviewers to explain their decisions. A useful explanation identifies the specific problem instead of saying only that an answer is poor. For example, "The answer is incorrect because it treats a possible exception as a universal rule" gives more information than "This response is bad."
The ability to explain a judgment clearly becomes particularly important in expert-level AI training projects.
- Willingness to follow a rubric
Annotators are not always asked to use their personal preferences. They are often expected to follow a defined set of criteria.
A response may not match a reviewer's preferred writing style and still satisfy the project's requirements. Good annotators distinguish their opinions from the standards they have been instructed to apply.
Is AI Data Annotation the Same as AI Training?
The terms are often used together in job advertisements, but they do not always describe the same work.
Data annotation usually refers to labeling, categorizing, transcribing, or otherwise preparing data for use in machine learning or evaluation.
AI training work is a broader term. It may include annotation, response evaluation, writing examples, comparing model outputs, correcting errors, or providing feedback that helps refine a system.
For example, an image annotator may label hundreds of pictures according to a defined set of categories. An AI response evaluator may compare two answers and explain which one better follows a prompt. A domain expert may develop challenging questions designed to test whether a model understands a subject.
These tasks can overlap, and companies do not always use job titles consistently.
The practical lesson is to read the responsibilities carefully. Look for the actual work involved, the skills required, the evaluation process, and the expected level of subject knowledge before deciding whether a role is suitable.
The People Behind AI Also Face Real Working Conditions
The importance of human annotation raises another issue: the people doing this work need clear instructions, fair treatment, and reasonable working arrangements.
In its discussion of best practices for data enrichment, Google DeepMind describes data labeling and model evaluation as forms of human work used to train and validate machine learning systems. The guidance also highlights issues such as appropriate payment models, worker selection, verified instructions, and regular communication. These concerns matter because annotation quality depends partly on the conditions in which people work.
Consider a project with unclear guidelines, changing requirements, and little opportunity to ask questions. Different annotators may interpret the same task differently, producing inconsistent results. If workers are expected to prioritize speed without understanding the quality standards, mistakes may become more common.
Clear instructions and effective quality checks help reduce these problems. Good project management also gives annotators a way to flag ambiguous examples rather than guess.
For job seekers, the working arrangement deserves attention too. Some AI training opportunities are freelance contracts tied to specific projects. Others may involve ongoing assignments, qualification tests, or variable task availability.
A remote listing should not automatically be treated as a stable, full-time job. Before accepting work, check the payment terms, contract conditions, expected workload, assessment requirements, and whether the company can confirm that the project is currently active.
How to Find Legitimate Remote Data Annotation Jobs
AI annotation and evaluation work can be accessible to people with different educational and professional backgrounds. However, finding a legitimate opportunity requires more than searching for "work from home AI jobs."
Start by identifying the kind of work you can realistically perform well.
Strong writing and research skills: Look for text evaluation, fact-checking, and response-review projects.
Language proficiency: Explore transcription, translation evaluation, and language-specific annotation.
Technical experience: Consider code evaluation, software-related tasks, or technical data labeling.
Subject-matter knowledge: Search for projects involving your academic or professional field.
Good listening and accuracy: Explore audio transcription and speech annotation where you meet the language requirements.
Once you identify a suitable category, research the company and the individual opening.
- Check the source of the job listing
Whenever possible, find the opening through the company's official website or verified application system. Confirm that the job title, responsibilities, eligibility criteria, and application process match the listing you found elsewhere.
Be cautious if a recruiter requests an upfront payment to secure a job, promises guaranteed high earnings without a credible explanation of the work, or asks you to share sensitive personal information through an unverified channel.
A legitimate opportunity should have a verifiable company behind it and understandable terms. You should be able to establish what the work involves, how payment works, and what information the company needs from applicants.
- Read the requirements before applying
Some projects accept applicants without previous annotation experience, while others require professional qualifications, language proficiency, or demonstrated expertise.
Check the accepted countries and regions carefully. A position described as remote may still be restricted to specific countries because of contractual, legal, tax, or project requirements.
Also, distinguish between joining a talent network and applying for a confirmed opening. Registration does not necessarily mean that work is immediately available.
- Prepare for qualification assessments
Many AI training projects use assessments to check whether applicants can follow instructions and meet the required quality standards.
Read every instruction carefully, answer based on the evidence provided, and avoid rushing. If you do not understand a rule, review the available guidance before submitting your work.
Do not assume that a qualification test is simply an exam of general knowledge. It may measure how accurately you apply a particular rubric, explain your reasoning, or handle edge cases.
You can use ExpertWoka to explore remote work, AI training opportunities, and other digital career options. As with any job platform, review each listing's requirements and application details before proceeding.
What This Means for People Building Careers Around AI
Human data annotation is worth understanding even if you do not plan to do it forever. For some people, it offers a way to apply existing skills to remote project work. A teacher may evaluate educational explanations. A researcher may check claims and assess evidence. A language specialist may review text quality. A developer may test AI-generated code.
The experience can also help workers understand how AI systems are evaluated, although annotation work does not automatically lead to a permanent role in AI development. Progress depends on the skills a person develops, the experience they gain, and the opportunities available to them.
People interested in building further expertise can focus on skills that transfer across projects: accurate research, clear writing, structured reasoning, subject knowledge, and consistent evaluation. Learning how to use annotation interfaces and follow project-specific quality standards can also help.
It is equally important to recognize the limitations. Freelance projects may end, task volumes can vary, and qualification requirements differ between providers. Treat the work as a specific professional opportunity, not a promise of effortless income.
The Human Work Behind Better AI
AI tools may appear to operate independently, but the process of building and evaluating them can involve many people making careful decisions behind the scenes. Those decisions influence which examples are used, how model responses are assessed, and whether mistakes are identified before a system reaches its users.
Human data annotators are not simply filling gaps until machines become capable enough to work alone. Their contribution includes defining and evaluating the standards by which AI systems are judged. As models take on more complicated tasks, that judgment remains important, particularly when accuracy, context, language, or specialist knowledge matters.
For anyone considering remote AI work, the best starting point is not chasing every listing with "AI" in the title. It is identifying a skill you can demonstrate, understanding the work a project actually requires, and finding a legitimate opportunity that values careful judgment. The technology may produce the answer, but people still help determine whether that answer deserves to be trusted.