Reinforcement Learning from Human Feedback, better known as RLHF, is one of the methods used to improve how AI models respond to people. While the name sounds like a job for machine learning engineers, many RLHF-related tasks are performed by human evaluators, writers, researchers, programmers, language specialists, and subject-matter experts. Their job is often less about building AI and more about judging what a good AI response should look like.
For anyone searching for remote AI training jobs, this distinction is important. You may not need to build a model or understand every part of reinforcement learning to work on a project involving human feedback. Depending on the role, you could spend your time comparing AI responses, checking facts, explaining errors, rewriting answers, or evaluating whether a model followed an instruction.
What is RLHF?
Reinforcement Learning from Human Feedback is a method for improving an AI model using judgments made by people. Instead of relying entirely on an automated measure of whether an answer is good, the training process can use human preferences as a signal.
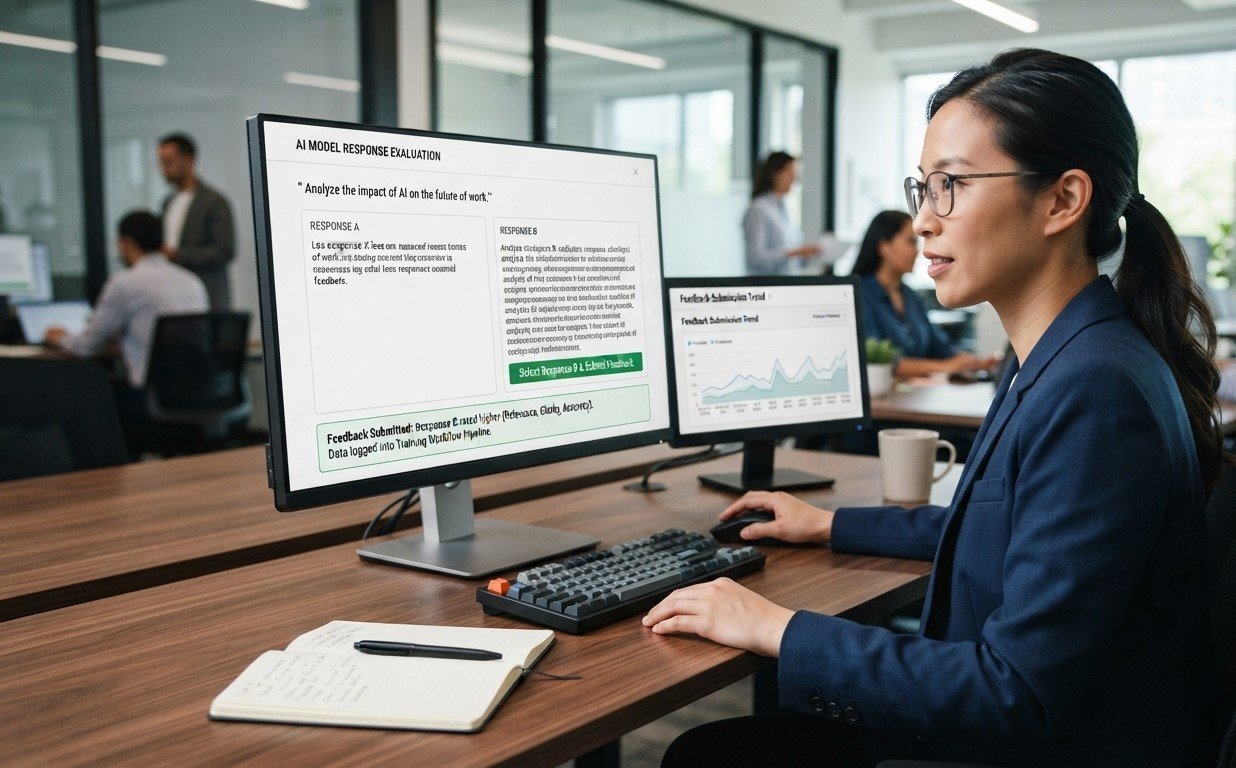
A simple example is comparing two answers to the same question. A human evaluator decides which response is better and may explain why. That information can then be used as training data to help the system learn which types of responses people prefer. OpenAI's work on InstructGPT describes this approach, where human labelers provided demonstrations and ranked model outputs before those preferences were used in further model training.
The basic idea is easier to understand than the terminology suggests:
AI generates responses → humans evaluate them → those judgments become training data → the model is adjusted using that feedback.
The actual technical pipeline can be considerably more complicated. It can involve supervised fine-tuning, preference data, reward models and reinforcement-learning algorithms. But for the person doing the human-feedback work, the task often starts with something much more familiar: reading an AI response and deciding whether it is good enough.
What do RLHF jobs actually involve?
There is no single job description called an “RLHF job.” Companies may use titles such as AI Trainer, AI Evaluator, AI Data Annotator, LLM Evaluator, AI Tutor, Model Evaluator, Domain Expert, AI Quality Analyst or Human Feedback Specialist for work that contributes to model training or evaluation.
The exact responsibilities depend heavily on the project. Scale AI's RLHF documentation, for example, describes tasks where contributors receive a prompt and multiple model-generated responses, indicate which response they prefer, and provide annotations or justification. The evaluation criteria can include instruction following, truthfulness, factuality, tone, helpfulness, safety and task completion.
That means an AI training task might look surprisingly ordinary on your screen. You could be given a question, two AI answers and a set of instructions telling you what to look for. Your job is then to make a careful judgment rather than simply choose whichever answer sounds nicer.
1. Comparing two AI responses
One of the clearest examples of RLHF work is response ranking.
Imagine a user asks an AI model: “Explain the difference between a lease and a licence in simple terms.” The system produces two answers. Response A gives a short, accurate explanation with a useful example, while Response B is much longer but confuses one of the legal concepts.
You might be asked to select the better response and explain your decision. This type of comparison is not about deciding which answer you personally like. You have to judge the responses against the project's criteria and the user's actual request.
Scale's RLHF documentation describes this type of preference annotation directly, including selecting a preferred model response and recording a justification for the choice.
This is one reason attention to detail matters so much in AI evaluation. A response can look good and still fail on one important requirement.
2. Checking whether an AI followed instructions
A response does not have to contain a factual error to be considered poor.
Suppose a user asks for five bullet points, with each bullet limited to one sentence. The AI provides five accurate paragraphs instead. The information may be correct, but the model failed to follow the requested format.
Instruction-following is therefore an important part of many AI evaluation tasks. You may need to check whether the model answered the actual question, respected the requested format, used the right tone, stayed within a specified length, or followed several conditions contained in the original prompt.
This can become difficult when prompts contain multiple requirements. A good evaluator reads the original instruction carefully before judging the response, rather than evaluating the answer in isolation.
3. Finding factual errors and hallucinations
AI-generated text can sound authoritative even when it contains an error. A human evaluator may therefore need to check whether claims, dates, calculations, citations, names, technical explanations or other details are actually correct.
This is particularly important in specialist AI training projects. A person with legal knowledge, for example, may be better equipped to spot a subtle problem in an AI-generated legal explanation than someone with no legal background.
The same applies to programming, mathematics, finance, science, medicine, history and other fields. You do not necessarily need to know how the model works internally if the project needs someone who understands the subject matter being evaluated.
4. Rewriting weak AI answers
Some human-feedback work involves more than choosing between existing responses. You may be asked to write a better answer yourself.
For example, an AI could provide an answer that contains the right information but explains it poorly. Perhaps it uses unnecessary jargon, misses an important qualification or fails to address part of the question. The evaluator may then rewrite the answer so that it is clearer, more accurate and more useful.
Scale's documentation distinguishes RLHF preference tasks from SFT tasks, where contributors write or rewrite model responses. Some RLHF workflows can also include rewritten preferred responses as part of the training data.
This is why good writing skills can be valuable in AI training. You are sometimes being asked to demonstrate, rather than merely identify, what a high-quality response should look like.
5. Providing specialist knowledge
AI companies may need people who understand specific subjects well enough to evaluate model outputs. A lawyer can review legal reasoning. A software developer can assess generated code. A mathematician can check a solution. A language specialist can evaluate grammar or translation.
The work is not necessarily about teaching the model everything you know. It is about using your knowledge to make reliable judgments about the quality of what the model produces.
That distinction matters for people searching for remote AI jobs because “AI experience” is not always the only qualification that matters. A company working on legal AI, for example, may have more use for someone with strong legal reasoning than someone who has spent years using general AI tools but has little understanding of law.
6. Evaluating safety and difficult prompts
Some AI evaluation projects are designed to find situations where a model behaves badly.
Instead of asking whether an answer is simply helpful, evaluators may test how the system responds to sensitive, misleading, adversarial or potentially unsafe requests. The goal is to identify weaknesses that developers can investigate and address.
This type of work can require careful judgment because the evaluator has to distinguish between a genuinely problematic response and one that appropriately refuses or limits a request.
Human feedback has always had a weakness here: the quality of the resulting system depends partly on the quality of the judgments supplied by human evaluators. OpenAI's earlier research on learning from human preferences explicitly discussed this limitation, noting that poor human understanding of a task can result in poor feedback.
That is one reason AI evaluation is not simply a matter of clicking “good” or “bad.” The person making the judgment needs to understand what they are looking at.
Do RLHF jobs require programming?
Not always.
This is one of the most useful things to understand before searching for RLHF work. There is a major difference between a person who works on the technical implementation of reinforcement learning and a person who provides the human feedback used in an AI training project.
A research engineer working on reinforcement learning might need machine learning knowledge, programming skills, statistics and experience with model training. Current AI-company roles show this clearly. Anthropic, for example, lists separate roles involving reinforcement learning, model evaluations, post-training, alignment and research engineering.
A human evaluator may instead spend most of the day reading prompts, reviewing model responses, researching factual claims, applying a rubric and writing short justifications.
Both types of work can be connected to AI training, but they are not the same career.
If you are searching for remote AI work and do not have a machine learning background, that does not automatically rule you out of human-feedback projects. You should focus on the actual task requirements rather than assuming that the acronym RLHF means you must be an AI engineer.
What does a typical RLHF task look like?
Consider a simple writing evaluation project.
You receive the prompt:
“Write a polite email asking a company to reschedule an interview because of a scheduling conflict.”
The AI produces three responses. You may then be asked to rank them and explain your decision.
Response A might be polite but too vague. Response B might clearly explain the situation but sound unnecessarily demanding. Response C might be concise, professional and directly address the request.
Your task could involve ranking the responses, identifying problems in each one, rating them against specific criteria and possibly rewriting the weakest answer.
A technical project could look completely different. You might receive a mathematical problem with two AI-generated solutions and be asked to determine which solution is correct, identify an error in the other one and explain your reasoning.
The interface changes from project to project, but the underlying skill is similar: make a careful, consistent judgment that can be used as useful data.
What skills do you need for RLHF work?
You do not necessarily need a computer science degree. For many human-feedback and AI evaluation projects, the most useful abilities are closer to research, writing and quality control.
- Good reading comprehension
You need to understand the original prompt before evaluating the answer. Missing one instruction can change your judgment completely.
- Clear written communication
Some projects ask evaluators to justify their rankings or explain why a response contains an error. Being able to make a short, precise argument is useful.
- Research and fact-checking
If an AI gives a questionable claim, you may need to verify it using reliable sources. Knowing how to distinguish a primary source from a random website is particularly valuable.
- Attention to detail
AI responses can fail in small ways. A single incorrect calculation, unsupported claim or missed instruction may matter even when the rest of the answer looks excellent.
- Subject expertise
Your existing profession or academic background can be an advantage on specialist projects. This is especially relevant when evaluating technical or professional content.
- Consistency
This may be the most underestimated skill. If you judge one response strictly and another similar response casually, the resulting data becomes less useful. Good evaluators learn to apply the same criteria repeatedly.
Why the word “RLHF” can be misleading when searching for jobs
If you search job boards only for “RLHF jobs,” you may miss relevant opportunities.
Companies and AI-data providers can use different names for work involving model evaluation, human feedback or post-training. Search terms such as AI Trainer, AI Evaluator, AI Data Annotator, LLM Evaluator, AI Quality Analyst, AI Tutor, Model Evaluator, Domain Expert, AI Response Reviewer and Human Feedback can uncover different types of projects.
Scale's documentation itself separates several project types, including Evals, RLHF, Rubrics and SFT. In other words, human contributors can be involved in different parts of the model-improvement process, even when their work looks similar from the outside.
This is useful when looking for legitimate remote AI work because the job title tells you less than the actual task description. Read what you will be doing before deciding whether a role matches your skills.
Is RLHF still relevant to AI training?
RLHF has been an important part of the development of instruction-following language models.
Research has continued beyond the earliest RLHF approaches. Anthropic, for example, has published research on using preference modeling and reinforcement learning from human feedback to train helpful and harmless assistants, including work involving repeated collection of fresh human feedback.
At the same time, RLHF should not be treated as a synonym for every form of AI training. Modern AI development involves several different stages and techniques, including data generation, supervised fine-tuning, evaluations, safety testing and other post-training methods. Scale's description of its data-engine work, separates RLHF from data generation, red teaming and model evaluation.
For job seekers, that distinction is useful. You do not need to limit your search to positions that explicitly mention RLHF.
The human part of AI training is bigger than the title suggests
The interesting thing about RLHF is that much of the human contribution happens before the technical terminology becomes visible.
Someone has to decide that one answer is more accurate than another. Someone has to notice that an apparently confident response contains a serious error. Someone has to determine whether the AI actually followed the user's instructions, and someone with specialist knowledge may have to explain why the answer is wrong.
That is why AI training work can be relevant to people who have never considered themselves “AI professionals.” A good writer, researcher, programmer, lawyer, teacher, mathematician or language specialist may already possess several of the skills required for human-feedback work.
RLHF is ultimately about turning human judgment into useful training information. The more capable AI systems become, the more important it is to have people who can tell the difference between an answer that merely sounds good and one that is actually good.
For someone looking for remote AI work, that is the part worth paying attention to. The job may not be to build the AI; it may be to teach it what better looks like.