One person might spend hours labeling images, transcribing audio, or categorizing text. Another might compare two chatbot responses and decide which one better follows the instructions. Someone else might test an AI model against a set of difficult questions and document where it fails. These tasks can overlap, and job titles are not always consistent, but they are not the same kind of work.
The easiest way to understand the difference is to look at what the human is trying to accomplish. Data annotation is mainly about creating or improving labeled data. AI training can involve using human-generated examples, preferences, corrections, or other feedback to improve a model. AI evaluation is about measuring how well an AI system performs against defined criteria.
That distinction matters if you are searching for remote AI jobs. A listing that says “AI trainer” may involve response ranking, writing, evaluation, annotation, or several of these tasks together. Knowing what the actual work involves is much more useful than relying on the job title.
What Is Data Annotation?
Data annotation is the process of adding labels, categories, transcriptions, or other useful information to raw data so that it can be used by machine learning systems.
The data could be an image, video, audio recording, document, or piece of text. A person might identify objects in an image, mark the boundaries of a vehicle, classify the sentiment of a sentence, transcribe speech, or identify specific entities in a document.
The basic idea is simple:
the human adds information that tells the system what the data represents.
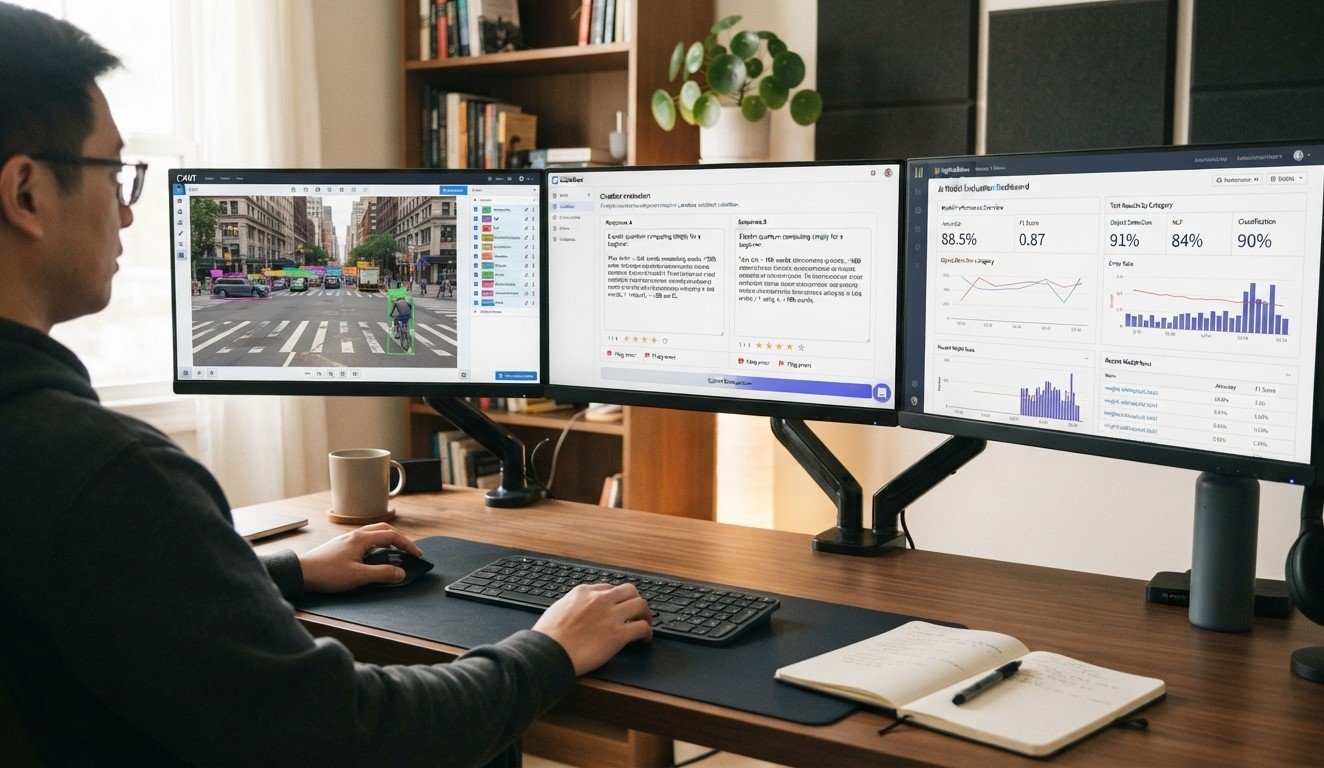
For example, imagine a collection of street photographs. If the project is building a computer vision system, an annotator might draw boxes around cars, buses, pedestrians, and motorcycles. Those labels give the training pipeline structured information about what appears in each image. Scale AI's current guide to data labeling describes annotation as assigning context or meaning to data so machine learning algorithms can learn from those labels. Scale AI's guide to data labeling
Data annotation is not limited to images.
A language project could require workers to classify text according to predefined categories. An audio project might involve listening to recordings and producing accurate transcripts. Other tasks can involve named-entity recognition, sentiment classification, content categorization, or marking specific sections of a document.
What does a data annotator actually do?
A typical annotation task may look something like this:
Read the project instructions.
Open an item such as an image, audio file, or text sample.
Identify the information the project asks for.
Apply the correct label, category, transcription, or markup.
Check the work against the guidelines.
Submit the completed item for quality control.
The difficult part is often not clicking the label itself. It is understanding the instructions and applying them consistently.
Suppose the instruction says to label a person only when their entire body is visible. You may encounter an image where someone is partly hidden behind a car. The task becomes a judgment call. Good annotation requires you to follow the project's definition rather than simply choosing the label that feels reasonable.
This is why annotation projects often use detailed guidelines, benchmark tasks, quality checks, and multiple layers of review. Clear instructions and consistent labeling are important because poor-quality labels can affect the usefulness of the resulting dataset.
What Is AI Training?
AI training is a broader term, and this is where much of the confusion starts.
An AI model does not automatically become better simply because humans interact with it. Depending on the project, human-generated data, demonstrations, preferences, corrections, evaluations, or other forms of feedback can become part of a process used to improve a model.
One well-known example is reinforcement learning from human feedback, or RLHF. In OpenAI's work on InstructGPT, human labelers wrote demonstrations of desired behaviour and ranked model outputs. The resulting human feedback was used as part of the process for fine-tuning the model. OpenAI's explanation of InstructGPT and human feedback
This gives us an important distinction.
A data annotator may be labeling the information that becomes training data. An AI trainer may be asked to produce examples, assess model responses, rank alternatives, correct outputs, or provide other feedback designed to improve model behaviour. The exact work depends heavily on the project.
In practice, the boundary is not always clean. A task can involve both annotation and training because an annotation itself can become part of a dataset used to improve an AI system.
What might an AI trainer work on?
An AI training project could ask a worker to:
Write an ideal answer to a prompt.
Compare several AI-generated responses.
Rank responses from strongest to weakest.
Identify factual or reasoning errors.
Rewrite an answer to make it more useful.
Check whether an AI followed specific instructions.
Classify a response according to a project rubric.
Provide preference data between different outputs.
Create examples that demonstrate a desired behaviour.
For instance, you might receive this prompt:
“Explain Nigerian constitutional law to a first-year university student.”
The model produces three answers.
Answer A is accurate but full of complicated legal terminology. Answer B is easier to understand but contains a factual error. Answer C is clear, accurate, and directly answers the question.
Your job might be to rank the three responses and explain why one is preferable.
That is quite different from drawing a box around a car in an image. Both tasks involve human judgment, but the type of judgment is different.
What Is AI Evaluation?
AI evaluation, often shortened to AI evals, focuses on measuring how well an AI system performs.
Instead of asking, “What information should we add to the dataset?” the evaluation question is closer to:
“How well does this model perform on the task we care about?”
An evaluation can test things such as accuracy, instruction-following, reasoning, safety, factuality, coding ability, or performance on a particular domain.
Some evaluations are straightforward. Give a model a question with a known answer and check whether it gets the answer right.
Others are much harder.
For an open-ended chatbot response, there may not be one perfect sentence that counts as correct. A response could be factually accurate but fail to follow the user's instructions. It could answer the question correctly but leave out an important qualification. It could be helpful but contain a subtle safety problem.
Anthropic has described AI evaluation as a difficult problem precisely because many model behaviours are subjective and because evaluation methods can produce misleading results if the test itself is poorly designed. Anthropic's discussion of AI evaluation challenges
AI evaluation therefore requires more than simply checking whether an answer “looks good.”
What does an AI evaluator do?
Depending on the project, an evaluator may:
Run predefined prompts against an AI system.
Compare outputs from two or more models.
Score responses against a rubric.
Check factual accuracy.
Test whether instructions were followed.
Look for harmful or unsafe behaviour.
Identify recurring failure patterns.
Review model performance on specific domains.
Record evidence supporting a rating.
Help improve or refine the evaluation criteria.
Some evaluation systems are automated, while others require human judgment. Anthropic's work on model evaluations, for example, describes human A/B testing in which people compare outputs and assess qualities such as helpfulness or harmlessness.
AI Training vs Data Annotation vs AI Evaluation
The easiest way to separate the three is to focus on the question each type of work is trying to answer.
There is overlap between them.
An annotation can become training data. A training task can involve evaluation. An evaluation can produce annotations or ratings that are later used to improve a model.
So these should not be treated as three completely separate industries.
They are better understood as different functions within the larger AI development process.
Where the Three Types of Work Overlap
This is particularly important when looking at remote AI jobs.
A company might advertise a role as an “AI Trainer” but give successful applicants tasks involving response evaluation, ranking, annotation, rewriting, or fact-checking. Another company might call similar work “AI Data Specialist,” “AI Evaluator,” “Data Annotator,” or “LLM Evaluator.”
The title alone does not tell you enough.
Look at the actual task description.
If the listing repeatedly talks about bounding boxes, polygons, image classification, transcription, segmentation, or labeling predefined categories, you are probably looking at data annotation.
If it talks about writing ideal responses, comparing model outputs, ranking answers, correcting generated text, or providing preference feedback, it is closer to AI training or human-feedback work.
If it talks about benchmarks, test sets, scoring rubrics, model comparisons, red teaming, failure analysis, or measuring performance, it is more closely related to AI evaluation.
There can still be overlap, but the primary purpose becomes clearer.
What Skills Do These Jobs Require?
The skills overlap more than the job titles suggest.
Data annotation skills
Annotation work usually rewards:
Attention to detail
Ability to follow instructions precisely
Consistency
Basic computer skills
Careful reading
Patience
Ability to recognize categories or patterns
For language or regional projects, language ability and cultural familiarity can also matter. Scale's current data-labeling guidance specifically discusses the importance of choosing annotators with appropriate language or domain knowledge for certain datasets.
AI training skills
AI training work often places more weight on:
Strong written communication
Critical thinking
Research ability
Understanding instructions
Ability to explain why an answer is better or worse
Subject-matter knowledge for specialist projects
Consistency when applying a rubric
The important skill is not simply knowing how to use ChatGPT. You need to recognize when an AI response is weak and be able to explain what needs to change.
For example, saying “Answer B is better” is much less useful than identifying that Answer A ignored the user's requested format, Answer B followed the instructions but contained an unsupported claim, and Answer C satisfied both requirements.
That level of reasoning is what makes human feedback useful.
AI evaluation skills
Evaluation work can require many of the same abilities, but with greater emphasis on measurement and consistency.
An evaluator needs to understand the evaluation criteria, apply them consistently, notice edge cases, and avoid changing the standard simply because one answer sounds convincing.
For specialist evaluations, subject knowledge can become particularly important. Anthropic's guidance on developing third-party evaluations recommends domain expertise when an evaluation measures expert-level performance in a specific subject.
That is why someone with a background in law, medicine, mathematics, programming, finance, languages, or another specialist field may encounter AI evaluation projects that specifically value their knowledge.
Is AI Training the Same as Data Annotation?
No, but the two can overlap.
Think of annotation as adding information to data, while AI training work can involve using human examples or preferences to shape model behaviour.
A simple example makes the difference clearer.
Suppose you receive 1,000 customer-support messages and classify each one as “billing,” “technical issue,” “account access,” or “other.” That is annotation.
Now suppose an AI produces responses to customer-support questions and you compare those responses, identify which ones are more useful, and rewrite poor answers. That is closer to AI training through human feedback.
Neither task is automatically more advanced. They simply require different types of human input.
Is AI Evaluation the Same as AI Training?
Again, not exactly.
Training is generally concerned with improving the system, while evaluation is concerned with measuring the system's performance. The distinction becomes obvious if you think about a student taking an exam.
Studying and practicing are not the same as sitting for the exam. The exam tells you how well the student performs under the test conditions.
AI systems work differently from students, of course, but the analogy is useful. Training-related work supplies information or feedback that can contribute to improvement. Evaluation creates a structured way to determine whether the model performs well against a particular standard. The two can also form a loop.
A model is tested. Evaluators discover a recurring problem. That problem informs new training data or feedback. The model is improved. It is tested again.
Scale AI describes this kind of broader cycle as collecting and curating data, training models, evaluating them, and repeating the process. Scale AI's overview of the AI data and evaluation cycle
What About Ordinary Data Annotation Jobs?
This is where people searching for remote work should pay attention. Not every AI-related job requires you to understand large language models, machine learning theory, or reinforcement learning.
Some projects are still fundamentally about careful annotation.
You may spend a work session listening to recordings and checking transcripts. Another project may involve categorizing text. Another might involve reviewing images and marking objects. These jobs can be part of the data pipeline that supports machine learning systems without requiring the worker to train a model directly.
At the same time, some newer AI data projects involve more complicated language tasks, preference ranking, response evaluation, or specialist review.
That means “AI job” is too broad a category to be useful on its own. The actual task matters more.
How Can You Tell What a Remote AI Job Really Involves?
Before applying, look past the title and ask five questions:
1. What will I actually review?
Is it text, images, audio, video, model responses, prompts, or something else?
2. What decision am I expected to make?
Are you applying a predefined label, ranking responses, correcting information, or scoring performance?
3. Is there a rubric?
A detailed rubric usually tells you a lot about the type of judgment involved.
4. What happens to my work?
The listing may explain whether your output is used for annotation, model improvement, evaluation, quality assurance, or another purpose.
5. What skills are being tested?
If the role emphasizes language accuracy, domain knowledge, reasoning, or response quality, it may be very different from an image-labeling project.
This approach can save you from applying to a role simply because the title contains “AI.”
Which Type of AI Work Is Right for You?
There is no single path into AI-related remote work.
If you are highly detail-oriented and comfortable following precise instructions, data annotation may make sense.
If you enjoy writing, comparing answers, researching facts, and explaining why one response works better than another, AI training or human-feedback work may be a closer fit.
If you enjoy testing systems, applying scoring criteria, finding failure patterns, and thinking about whether a test actually measures what it claims to measure, AI evaluation may be more relevant. And you do not necessarily have to choose only one.
A worker who starts with annotation can develop experience with quality review. Someone doing response evaluation may move into more specialized AI training projects. Someone with strong subject-matter knowledge may eventually qualify for domain-specific evaluation or training work.
The important thing is to understand what you are actually doing rather than chasing whichever AI job title happens to be popular.
Final Thoughts
The difference between AI training, data annotation, and AI evaluation becomes much clearer when you stop looking at the job titles and look at the purpose of the task.
Data annotation adds structured information to data. AI training uses data, examples, corrections, or human feedback to help improve model behaviour. AI evaluation tests how well a model performs against a defined standard.
In real remote jobs, the boundaries can overlap. A single project may involve annotation, evaluation, and training-related tasks, which is why reading the actual job description matters more than the title.
If you are looking for AI work, start by asking a simple question before you apply: “What exactly will I be judging, changing, or labeling?”
The answer will usually tell you far more about the job than the words “AI trainer” ever could.